Zed: JSONL/NDJSON previews
zed-industries/zed · Merged PR · Rust
Zed has a tabular preview that shows CSV, TSV and other delimited files as a sortable, filterable table. JSON Lines files, one JSON object per line, had no preview, though it's a common format for logs and datasets. It's also what ProofRAG uses for golden sets and predictions.
The Problem
Opening a .jsonl or .ndjson file only gave you the raw text. While building the new path I also hit a crash in the existing CSV preview. After an edit that removed rows, the preview kept the old display-to-data row mapping until a background filter and sort task rebuilt it, so rendering could look up rows that no longer existed.
What I Changed
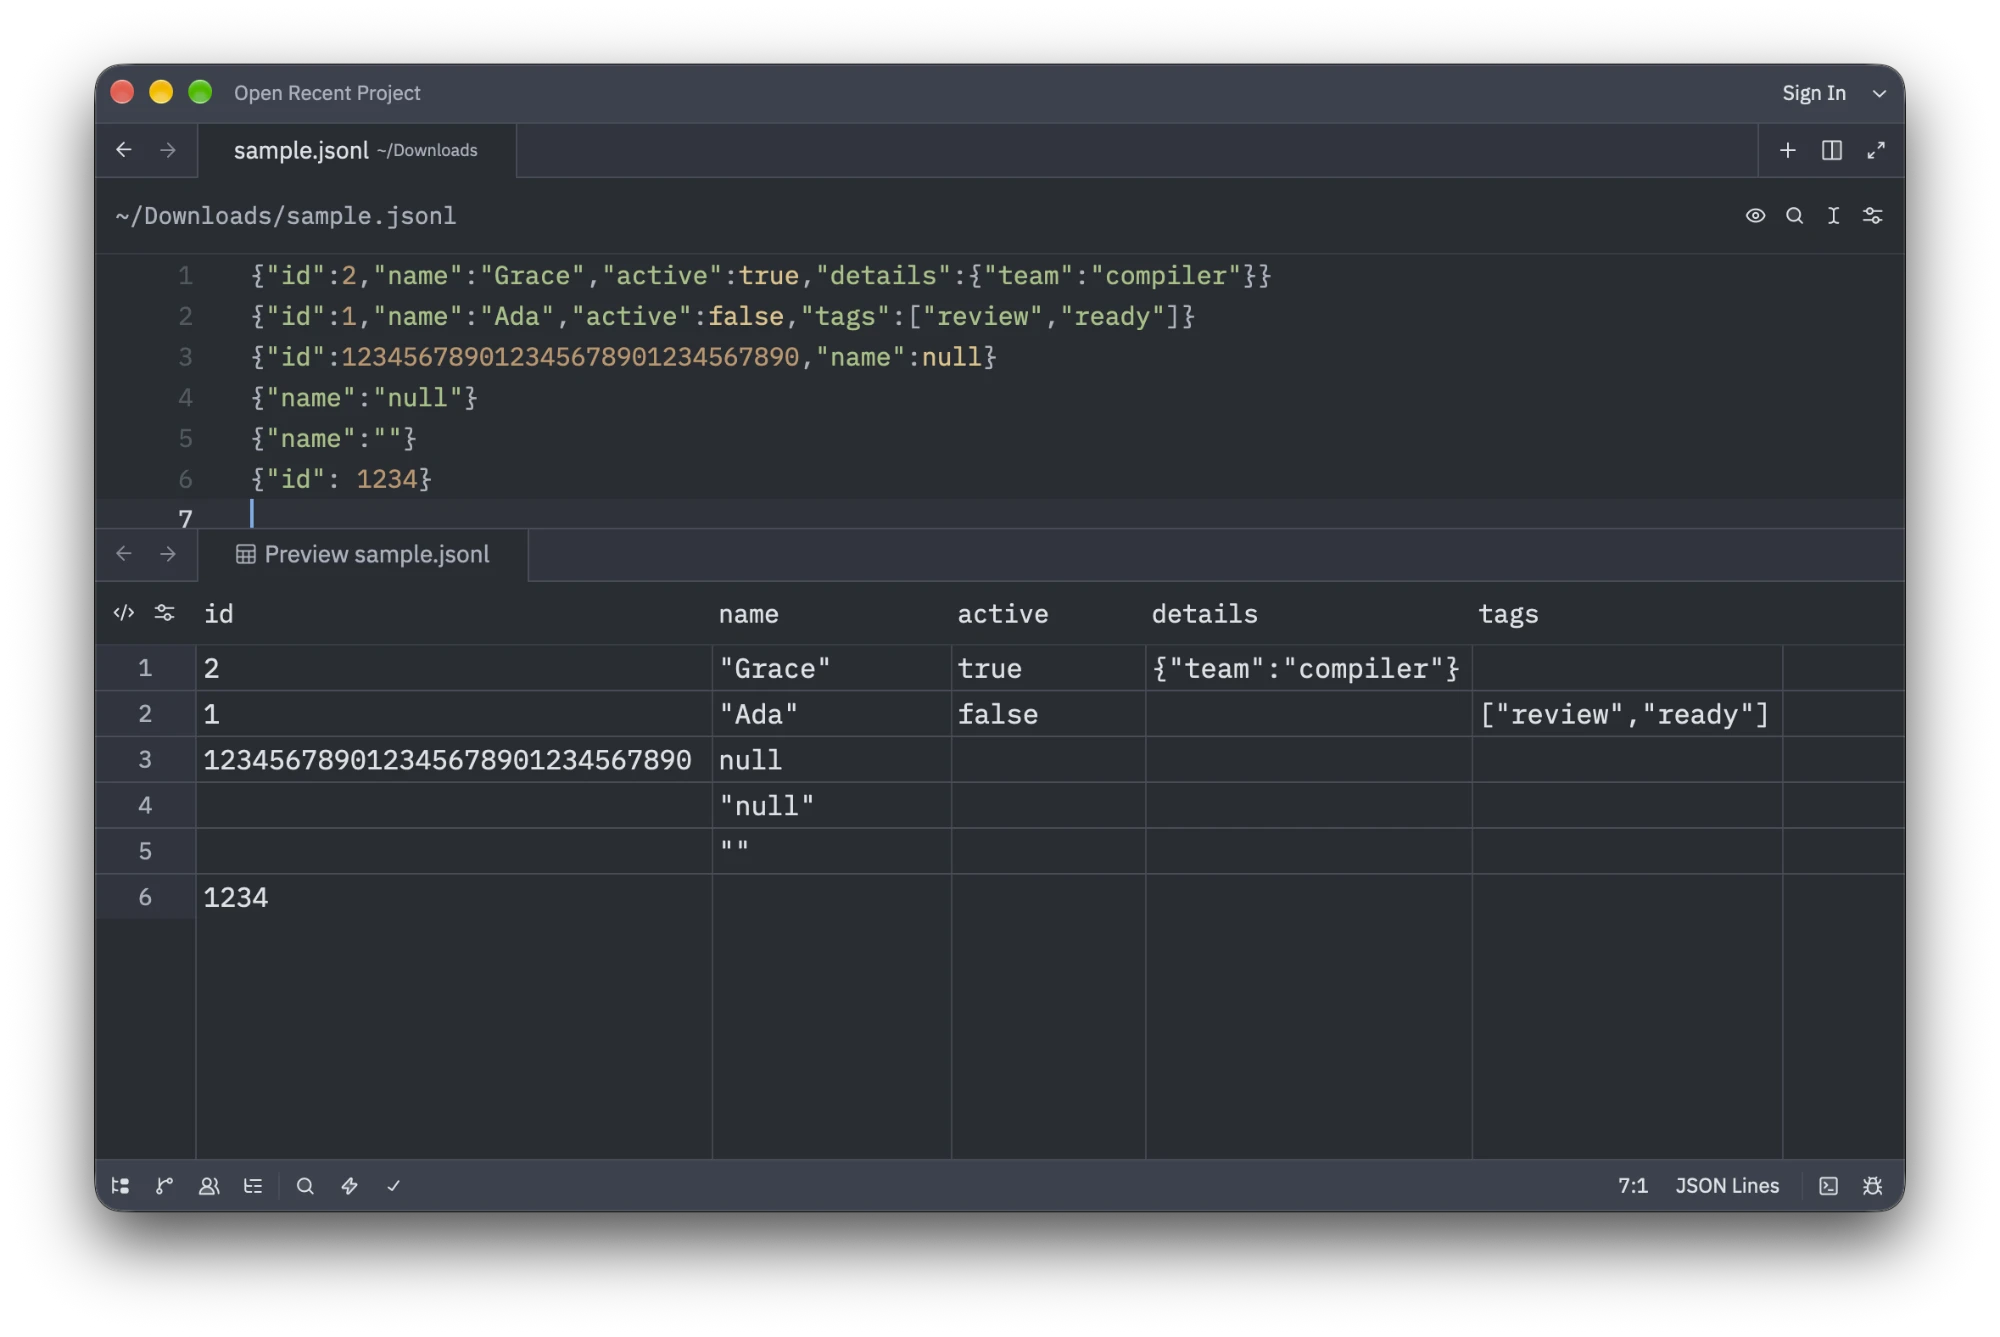
details and tags join from later records. The long id stays unrounded, nested values stay compact JSON, and null, "null" and "" remain three different cells. Parsing. Each nonblank line is parsed into an ordered map of keys to serde_json raw values. Top-level keys become columns in first-seen order. Values keep their JSON text, so numbers are never re-serialized and rounded, nested objects and arrays show as compact JSON, and a missing field, null, "null" and "" stay distinct. Raw values borrow from the buffer, so every cell keeps its exact source position, even when the same value repeats.
Edit recovery. The preview re-parses as you type. An invalid record replaces the table with an error that names its source line, and the table comes back once the line is fixed. Filters and sorting are stored by column index, so they survive edits that keep the columns and are cleared when the column names or order change.
The CSV fix. Setting new contents now clears the stale mapping, and the table sizes itself from the mapping's visible row count rather than the raw row count.
Docs and keymaps. A JSON Lines section in Zed's JSON docs, and the existing preview shortcuts extended to both extensions on macOS, Linux and Windows.
Testing
Parser unit tests cover column order, value fidelity, source spans and line numbers, empty input and empty objects, error line numbers and format dispatch. Two UI-level tests drive a real editor and preview. The CSV test deletes multi-line quoted rows through a series of edits and checks, on every update, that each displayed row still points at a real row. It runs for 20 iterations. The JSONL test sorts and filters, breaks line 2, checks the error names it, fixes it, and confirms the filter survived. Adding a column then has to clear it.
I checked the preview by hand on macOS only. Windows, Linux and large-file performance were not tested, and the PR says so.
Review
A reviewer suggested moving the render-readiness condition into a helper and asked how the new Generated cell (a column heading with no source span) differs from the existing Virtual one (a missing field). Both became a second commit: the helper, plus a doc comment on the type. The reviewer also pointed out that line anchors would make future inline editing easier than cell anchors, which I've left for a follow-up. A maintainer pushed a typo fix, approved, and sent it through the merge queue.
The main lesson was to fit the existing design rather than add to it. The new parser feeds the table engine the crate already had, filters and sorting keep their current behaviour, and the new cell type sits beside the old ones. Zed's own test harness did the rest: a UI test that checks every intermediate update is what pinned the CSV crash down, and it now guards against it coming back.
Outcome
Merged on 24 September 2026 as my first contribution to Zed. The pull request has the full diff and discussion.
Pull request
- Opened
- 18 September 2026
- Merged
- 24 September 2026
- Crate
- tabular_data_preview
- Files changed
- 12
- Lines
- +607 / −30